← Journal · · Deep dive
Why ML images take so long to deploy
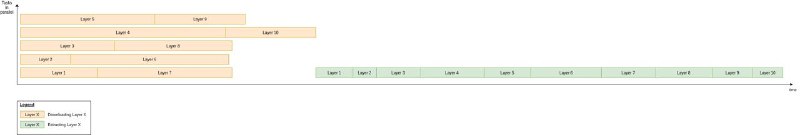
Hey everyone! It's been a while since my last post, and I want to share one of my research findings) I ran into the following problem: in the ML world, docker images are built with extra fat, all the libraries weigh a lot, plus CUDA is at least 5-6 gigs. In total you get well over 10-15 gigs for a single image😱 Imagine building an autoscaling system, say, in Kubernetes. When autoscaling kicks in, a new node comes up (it's bare, none of the images you use are there). In one of my cases, deploying a new replica ended up taking around 10 minutes (2 minutes for the node to come up, 8 minutes to pull and set up the container image). Quite long, especially if you want a system without delays (so you don't lose customer traffic)
I started researching image caching (somewhere near the nodes), here you can see various solutions (though on Medium you might need a VPN to access it). I deployed a caching registry in the cluster, but only won on layer download speed (they download in parallel, cutting it from 8 minutes down to 6). The problem turned out to be extraction (it's single-threaded, and if a layer is 5+ gigs, unpacking takes quite a while). The chart shows exactly how layer pulling and extraction happen