← Journal · · Note
NVIDIA open-sourced Run:ai: a complete platform for GPU clusters
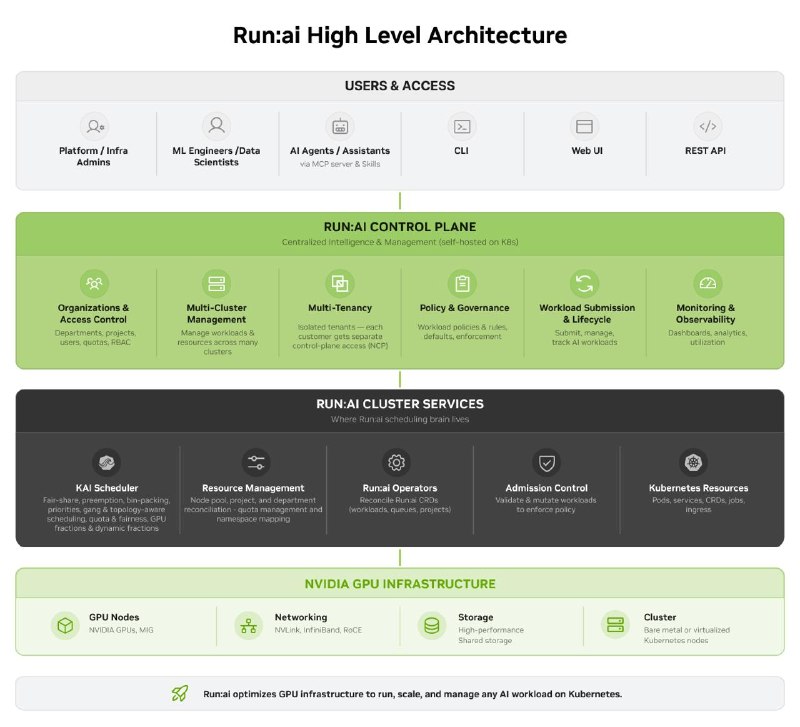
Hey everyone! NVIDIA open-sourced the entire Run:ai platform. Previously only the KAI scheduler was open source, but now the full platform is available under Apache 2.0.
Here's what it includes:
- control plane - workload management, quotas, policies and access control, single entry point for multiple clusters;
- cluster services - controllers and admission webhooks in each cluster;
- KAI Scheduler - gang scheduling, fair-share, bin-packing, topology and DRA, already in CNCF Sandbox;
- installer, CLI, web UI and REST API.
Everything except KAI lives in a monorepo.
What they released for the first time and is worth checking out:
📌 GPU Fractioning - fractional GPUs on native CUDA 13.4 fractions with hard memory isolation. Previously fractions in KAI were essentially time slicing, so it's interesting to see what they're offering now.
📌 KAI Resource Management - projects and departments with quota hierarchies, node pools for different hardware
📌 Workload Map - a single abstraction over different CRDs: PyTorchJob, RayCluster, JobSet and KServe InferenceService
📌 MCP server - Run:ai operations as tools for AI assistants
📌 Platform load tests and local Kind setup in one command - in the same monorepo
Also announced nearby - Model Streamer for fast weight loading (already built into vLLM and SGLang) and Grove from NVIDIA Dynamo for orchestrating multi-component inference.
Essentially, the Kueue + HAMi combination now has an open alternative "in one box": quotas, GPU fractions and multi-cluster, which is great to see. Going to dig deeper into what's inside :)