← Journal · · Note
Sticky sessions vs EPP: how to route requests in LLM
Hey everyone! In my last post, the comments discussed inferencePool in llm-d, so I decided to show you the results of comparing traffic routing in llm with and without it.
In KServe 0.18, LLMInferenceService routes requests through InferencePool from Gateway API Inference Extension. The Gateway (Envoy) asks EPP (Endpoint Picker) which replica to send the request to before proxying, and EPP looks at the KV cache prefixes and queue of each replica. A simpler option is sticky sessions through consistentHash in Istio: one session = one replica. The question is: is EPP worth the hassle?
Setup: Qwen3-1.7B × 6 vLLM replicas on one H100 (split via MPS), llm-d-inference-scheduler 0.7.1, Istio 1.28, load via aiperf, cache cleared before each run. I compared round-robin, sticky, EPP approximate, and EPP precise.
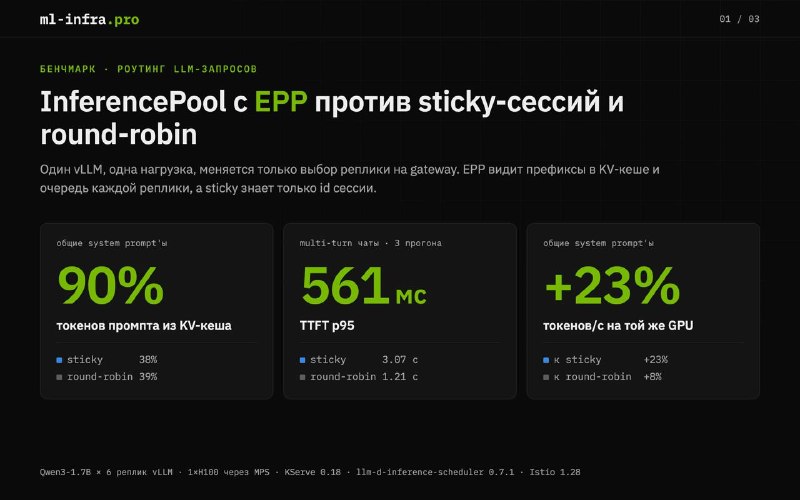
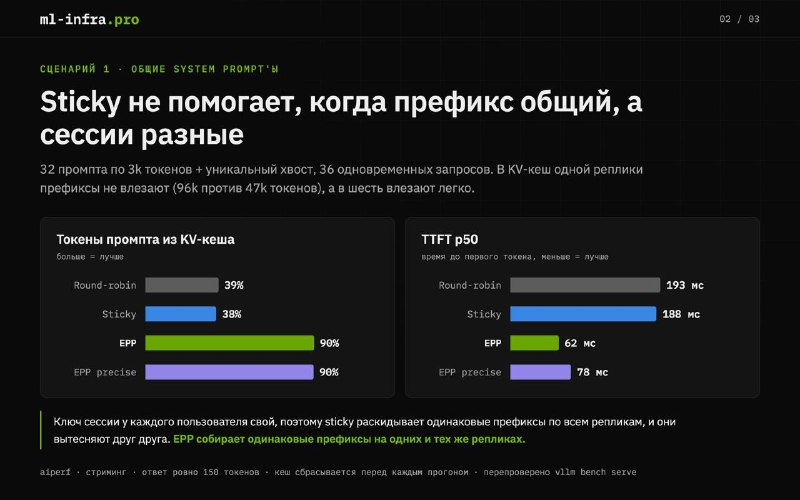
1️⃣ Common system prompts (agents, RAG instructions). Sticky is useless here: each user has their own session key, and identical prefixes scatter across all replicas. Cache hit: EPP 90%, sticky 38%, round-robin 39%. TTFT p50 is 62 ms versus 188 ms with sticky, and tokens/sec on the same GPU is +23%.
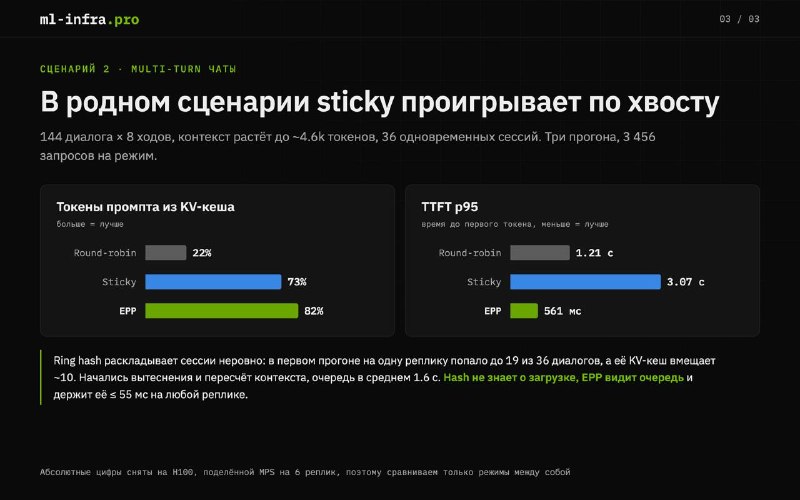
2️⃣ Multi-turn chats - the native sticky scenario. On cache it almost catches up (73% vs 82%), but loses on the tail: TTFT p95 is 3.07 s vs 561 ms. Ring hash distributes sessions unevenly: one replica got up to 19 out of 36 dialogs, but its KV cache holds about 10. Then evictions, context recalculation, and queueing. Hash knows nothing about load, but EPP sees the queue and doesn't let the replica choke.
3️⃣ Approximate vs precise. Precise sees the actual KV cache contents via ZMQ events from vLLM, but gave no win: parity on common prefixes, even worse on multi-turn (78% vs 83%). Plus it's way harder to configure: tokenizer sidecar, ZMQ, block size alignment. My hypothesis: when the cache is full, precise honestly sees "no cache anywhere" and routes the next turn to another replica, while approximate remembers which replica it sent the session to. So I'd recommend starting with approximate.
If your LLM runs on multiple replicas, sticky sessions won't replace routing that accounts for cache and queue. That's how it is.